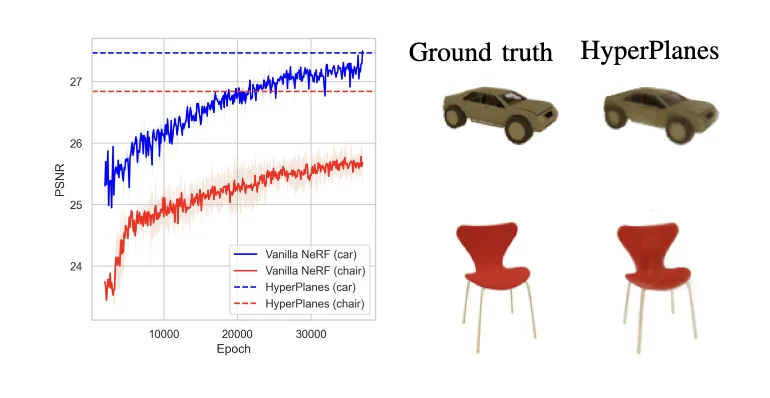
Neural radiance fields (NeRFs) are a widely accepted standard for synthesizing new 3D views of objects from several base images. However, NeRFs have limited generalization capabilities, meaning we need to use significant computational resources to train individual architectures for each object we want to represent. To address this issue, we propose a few-shot learning approach based on the hypernetwork paradigm that does not require gradient optimization during inference. Instead, the hypernetwork gathers information from the training data and updates universal weights. As a result, we have developed an efficient method for generating a high-quality 3D object representation from a small number of images in a single step, applicable in various use cases, such as robotic teleoperation. We confirmed this by directly comparing our method with state-of-the-art solutions.
Authors: Paweł Batorski, Dawid Malarz, Marcin Przewięźlikowski, Marcin Mazur, Sławomir Tadeja, Przemysław Spurek